





11-04-2019, 11:47 AM
(This post was last modified: 11-04-2019, 12:15 PM by -JKP-.
Edit Reason: fixed the EVA characters, added another picture
)
Quote: Mark: JKP: It seems to me that there must be a greater number of blocks than there are characters.
i.e. two characters $ and &
four distinct two character long blocks
$&
&$
$$
&&
three characters -> 27 distinct three character long blocks
In other words when you start using blocks instead of individual characters the size of the equivalent character set possible mappings hugely increases.
So you may run of characters to represent the alphabet, but you don't run out of blocks to represent the alphabet, at all, in fact you have more than enough.
I'm quite aware of this. It only takes 3 characters to create numerous combinations if they are grouped in twos.
But, this is why I bring up the VMS characteristic of positionality. The VMS is different from substitution ciphers in the way it is structured.
It's not just the position in tokens that is rather rigid, the combinations of tokens are also quite rigid.
These patterns that you posted:
$&
&$
$$
&&
Are very un-VMS-like (yes, I know it's an example, but this example specifically goes contrary to how the VMS is structured).
The VMS tends to have $& but not &$, and only a few characters (mainly ee and ii) are written as $$. Most of the others do not occur in the combinations you suggest.
Example 1: Extremely common biglyph pattern ar
You will find almost 4,000 of occurrences of ar but it is uncommon to find ra (less than 1,000 occurrences BUT the number is MUCH smaller if you accept that there may be other biglphs because it turns out that the first character is actually part of the previous also very common biglyph).
Also, you will not find rr, or aa (only a dozen occurrences and some of those might be "o" rather than "a", it's hard to tell which it is, plus the second "a" is almost always part of an ain sequence and MIGHT be part of an ain "block").
So, out of four combinations based on one of the most common pairs in the VMS, only one is used with any frequency, and the others are rare to nonexistent.
Example 2: Extremely common biglyph pattern dy
There are almost 7,000 occurrences of dy, but there are only a couple of hundred yd and if you look closely at what they are, then you find that the d is usually the beginning of a dain sequence (which is possibly a different block) and that the y is actually part of a preceding dy (in other words dydy occurs but #dy where the previous one is not another dy pair generally does not).
The combinations yy and dd are rare and when dd DOES happen, it's usually d preceding the very common dy combination. In other words, it would have to steal part of the adjacent biglyph to be valid.
Example 3: Extremely common biglyph che
There are almost 5500 occurrences of che, but only about 124 occurrences of ech and those 124 occurrences are almost always stealing the e from a preceding biglyph.
There are only 13 occurrences of chch and occurrence of ee (which is frequent) might not be a combination-variation of che because there are sometimes 4 in a row, which means the ee might have to be considered on its own merits to be a biglyph (and might be similar to the minims in daiiin).
These are not isolated examples. The text very much works in this way. ar al or ol dy ot che cho ee od (and a few others) occur so frequently and almost always in the same order that I gave them a name, I call them Janus pairs. An extremely high proportion of the manuscript is composed of these simple patterns.
In theory, you can get many combinations by swapping them around. But in the VMS, these various combinations of characters occur less frequently than in natural languages, and significantly less frequently than in theoretic proposals of possible combinations.
I'm not saying biglyphs can't correspond to letters, it's quite possible that they do (I've been trying to make sense of possible multiglyphs for quite a number of years, as you can see from the chart below), but the various combinations of letters that we would expect in natural languages or even in a constructed language based on swapping them around to create more combinations, is quite different from what we observe in the VMS—most of the combinations are one-directional and when they appear to be two-directional, it's often an illusion caused by them being preceded by another instance of the same combination.
This is something I've blogged about in the past, but here's a simple example where I assessed the text for potential biglyph candidates:

Here's an example of Voynich text that I posted on my blog a couple of years ago:
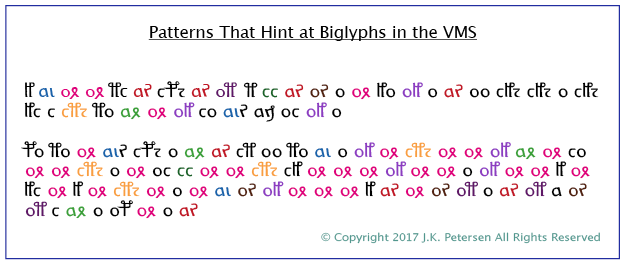
Look at ol and ar in particular, as they are probably the easiest to "see". Notice how they are directional.
A good example of text with clear block patterns (if you want to call them that) is You are not allowed to view links. Register or Login to view. . Look especially at the many ol or ololol che (and of course the aiin sequences).